Marketing Mix Modeling for B2B SaaS: When Is MMM Worth It?
Marketing mix modeling can tell a B2B SaaS team how to split budget across channels, but only with enough weekly history, real spend variation and experiments to calibrate it. Here's the readiness check, a worked dataset and what to do if you're not ready yet.
Published Nov 3, 2026.
Marketing mix modeling for B2B SaaS is worth it once you have about two years of weekly spend and CRM outcomes by region, channel budgets that actually moved, a weekly outcome that isn't mostly zeros, and incrementality tests to calibrate against. Short of that, a model can fit your history well and still point your budget the wrong way, so keep testing.
This picks up where my guide to incrementality testing for B2B SaaS without an MMM budget left off. That piece laid out the Lift Ladder, four rungs from a simple on/off test up to a calibrated MMM. This one is about whether, and when, to climb to rung 4. An MMM inherits every gap in the data you feed it, so if your tracking layer still needs work, my definitive guide to Google Analytics 4 is the better place to start.
Key takeaways
- Google's Meridian documentation gives a rule of thumb of at least two years of weekly data for a geo-level MMM and three years for a national one, and says the real answer depends on what your data is like.
- MMM answers a portfolio question: how to split next quarter's budget across channels. An incrementality test answers whether one channel causes pipeline right now, and attribution handles daily optimization.
- An MMM's estimates are causal only if every important confounder is measured, and Google's docs say there's no statistical test that can confirm that from your data. A good fit isn't proof.
- Calibrate with your own experiments, but treat each result as an estimate with its own uncertainty rather than exact truth.
- Google's Meridian and Meta's Robyn are free and open source. The real costs are analyst time, data engineering and the budget decisions that wait while the data matures.
What is marketing mix modeling, and what budget question does it answer?
Marketing mix modeling (MMM) is a statistical model that uses aggregated weekly data, such as spend, impressions and outcomes by channel and region, to estimate how much each channel contributed to a business outcome and how that contribution changes as spend changes. It answers one budget question: if I move money between channels next quarter, what happens to pipeline?
Media mix modeling is the same technique under another name. Google's Meridian repository describes MMM as a technique that "uses aggregated data to measure impact across marketing channels and account for non-marketing factors that impact sales and other key performance indicators (KPIs)." For a B2B SaaS team, that KPI is usually SQLs, opportunities or pipeline dollars from the CRM, not closed revenue.
The method is mainstream among large advertisers. The IAB's State of Data 2024 report found 70% of buy-side decision-makers (58% of brands and 83% of agencies) were investing or planning to invest in MMM because of legislation and signal loss. In a 2025 Kantar study with Meta, 34% of large advertisers said they prioritize MMM over other tools when making decisions. Those are companies spending more than $1 million a year on digital, so I'd read the numbers as proof the method is established, not as proof a Series B team needs one.
Because MMM works from aggregates, it doesn't need user-level tracking. Google's January 29, 2025 Meridian launch post says MMMs "measure performance in a privacy-centric way" for that reason. That doesn't make an MMM immune to tracking problems. If the SQL counts you feed it come from a form that misfires or a region field that's half empty, the model learns the gap as if it were demand (I covered the capture side in is server-side tracking worth it).
How do baseline demand, channel inputs, confounders, adstock and saturation work?
An MMM splits each week's outcome into a baseline, the share that would have arrived with no paid media, plus each channel's contribution and the effect of other factors you control for. Two transformations shape every channel's contribution: adstock spreads it across later weeks, and saturation makes each extra dollar worth less than the last.
Here's how each piece works, using Google's Meridian documentation as the reference.
- Baseline: Demand that arrives without paid media, from reputation, referrals, existing pipeline and sales outreach. Meridian handles trend and seasonality with a time-varying intercept, so separate seasonality variables aren't required unless you switch that off.
- Channel inputs: Weekly exposure for each paid channel, such as impressions or clicks, plus spend for the ROI math. Meridian's data guide requires these to be summable, so you feed clicks rather than click-through rate.
- Controls: Variables that affect both how you spent and what happened, which is what makes them confounders. Meridian's guide suggests asking your marketing planner what influenced budget decisions. In SaaS that's often outbound volume, pricing changes, launches and brand search demand.
- Adstock: Carryover. Meridian computes each week's media effect as a weighted average of that week and a set number of earlier weeks, with the weights decaying over time.
- Saturation: Diminishing returns, modeled with a two-parameter Hill curve. The docs warn that the curve is estimated from the observed range of spend, so extrapolated results "should be interpreted with an appropriate level of caution."
These pieces exist because simple regression misses how advertising behaves. Yuxue Jin and her Google co-authors put it plainly in their 2017 paper on Bayesian media mix models: "Advertising usually has lag effects and diminishing returns, which are hard to capture using linear regression."
B2B stretches the lag. If your KPI is opportunities and the median time from first touch to opportunity is two months, the adstock window has to cover those weeks, and a longer window is harder to estimate from the same history. Modeling SQLs or demo requests shortens the lag, and you can translate those into pipeline value afterward.
How is MMM different from attribution and incrementality tests?
Attribution assigns credit to the touchpoints it tracked, an incrementality test measures what one channel caused in one window, and an MMM estimates every channel's contribution from years of history. Each rests on different assumptions and supports a different decision, so a growth team needs more than one.
| Attribution (GA4, platform, multi-touch) | Randomized or geo incrementality test | Marketing mix model | |
|---|---|---|---|
| Decision it supports | Which campaign, keyword or creative to adjust this week | Whether one channel causes pipeline at current spend | How to split next quarter's budget across channels |
| Core assumption | The tracked path reflects what influenced the buyer | Randomization, or a control group that tracked the test regions before launch | Every important confounder is measured, and the adstock and saturation shapes fit reality |
| Granularity | User, session and campaign | One channel, the test regions and the test window | Channel by week, ideally by region |
| Feedback speed | Daily | Weeks of testing, plus time for pipeline to mature | Slow: years of history, and a refit to learn from new data |
| How uncertainty shows up | Usually not shown at all | A confidence interval or certainty level | Credible intervals on contribution, ROI and response curves |
The same Kantar study found 55% of large advertisers often get conflicting results from different measurement tools. I'd treat a disagreement as information. The experiment is the most direct evidence for one channel in one window. The MMM is the only one of the three that covers the whole portfolio at once.
When is a B2B SaaS business ready for MMM?
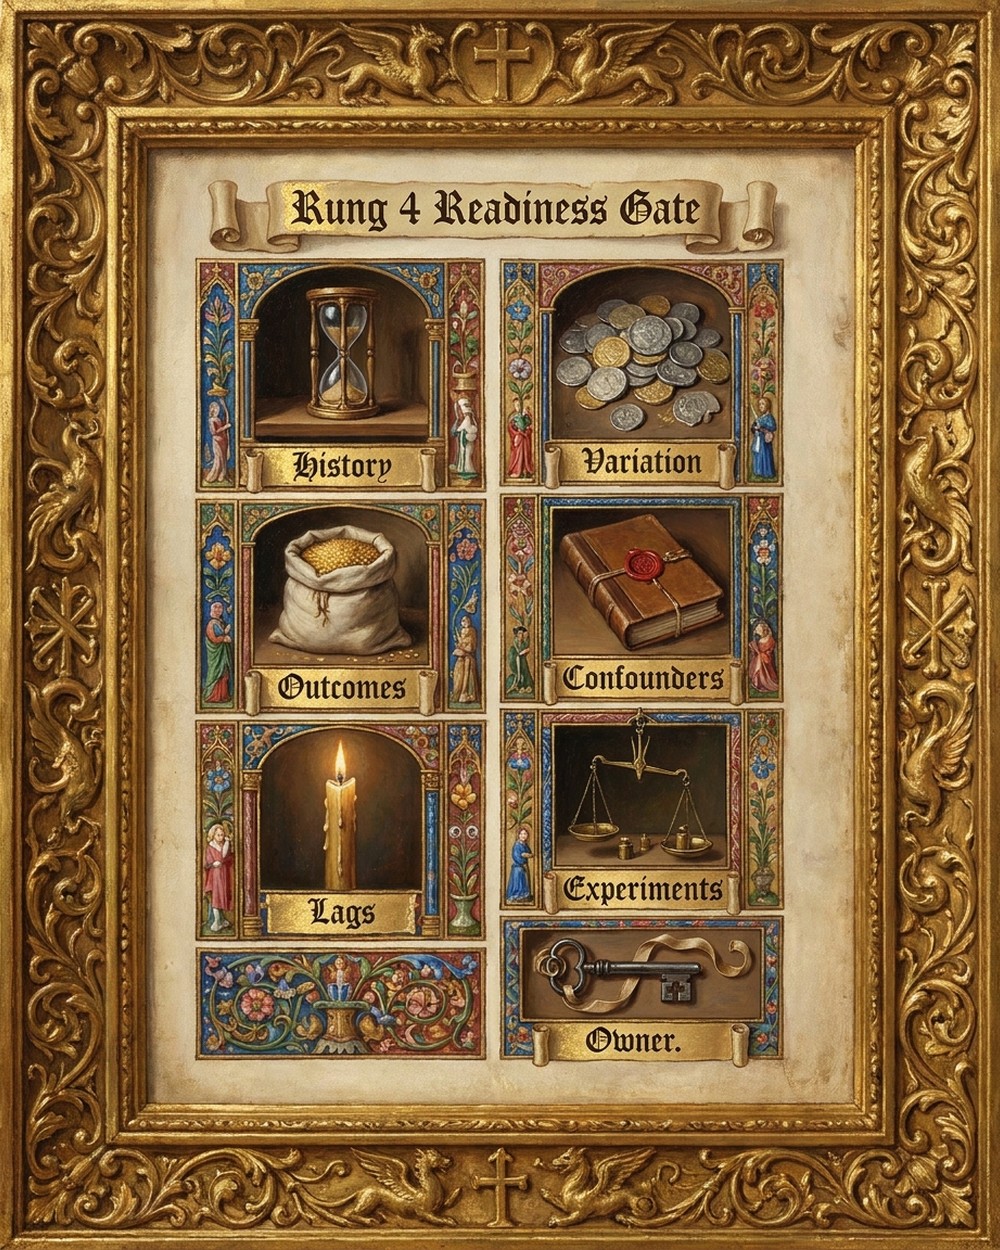
A B2B SaaS company is ready for MMM when it passes seven checks I call the Rung 4 Readiness Gate: enough comparable history, real spend variation, a dense outcome, logged confounders, lags the data can cover, experiments to calibrate with, and an owner. If History, Variation or Outcome density fails, or any two checks fail, I'd keep testing and come back to the model later.
- History: At least two years of weekly data for a geo-level model or three for a national one, per Meridian's rule of thumb, with channel and funnel-stage definitions that mean the same thing across the whole period. A redefined SQL resets the clock.
- Variation: Each modeled channel's spend moved meaningfully across weeks or regions. Yingxiang Zhang and co-authors at Google note in a 2024 calibration paper that MMMs "may fall short in precisely measuring effectiveness, especially for smaller media channels and channels with little spend variation."
- Outcome density: The KPI produces enough events per week, and per region, that most cells aren't zero. A few enterprise deals a month is too sparse.
- Confounders logged: A dated record of pricing changes, launches, outbound pushes, sales hiring and events, so each can enter the model as a control.
- Lags covered: The time from first touch to your KPI fits a lag window your history can support.
- Calibration evidence: At least one incrementality test on each of your biggest channels, from the lower rungs of the Lift Ladder.
- Ownership: An analyst who can run Python or R, read posterior diagnostics and explain an interval to a CFO, plus data engineering help to refresh the inputs.
The history check is mostly arithmetic. Meridian's guide to how much data you need works through a national model with 12 media channels, six controls and eight knots, which is 26 parameters. Two years of weekly data gives 104 data points, or four per parameter, which the docs call "too low to estimate the model reliably." Cutting to three channels, two knots and fewer controls, then using three years of data, gives 156 points for 10 parameters. That's roughly 15 per parameter, and the docs say you "might be able to glean some directional information."
Small samples also give the priors more pull. Jin and her co-authors found that "prior distributions have a big impact on the posteriors when the sample size is small and may lead to biased estimates." Structural change hurts in a similar way. A move upmarket, a new self-serve tier or a rebuilt sales team changes the relationships the model assumes held steady across the whole window.
What does a usable weekly dataset look like?
A usable dataset has one row per week, and per region if you can, holding spend and exposure for each channel, a summable CRM outcome counted by a consistent date, and the controls that shaped your plans. The example below is hypothetical, not a client, and it shows where SaaS data usually breaks.
Picture a hypothetical Series C company selling workflow software to U.S. mid-market teams. It spends on non-brand Google search, brand search, LinkedIn and Meta, runs an outbound team and changed its pricing once. It has 130 weeks of history and creates about 45 SQLs a week. A slice of its dataset might look like this.
| Week starting | Region | Non-brand search spend | LinkedIn impressions | Outbound emails sent | New pricing live | SQLs created |
|---|---|---|---|---|---|---|
| 2026-03-02 | Pacific | $9,400 | 182,000 | 2,150 | 0 | 14 |
| 2026-03-02 | Mid-Atlantic | $7,900 | 150,500 | 1,980 | 0 | 11 |
| 2026-03-09 | Pacific | $9,100 | 176,000 | 2,300 | 0 | 12 |
| 2026-03-09 | Mid-Atlantic | $8,200 | 149,000 | 2,050 | 0 | 9 |
Four decisions make or break that table.
- Outcome date: Count SQLs by the week they were created, not by the week the lead first arrived. Event-date counts are complete as soon as the week closes. Cohort counts tie outcomes to the week marketing touched them, but the latest cohorts haven't matured, so the model sees a slowdown that isn't real. If you use cohorts, drop or flag the weeks younger than your typical conversion time.
- Outcome choice: Pipeline dollars are summable, but one large opportunity can swing a week. SQL and opportunity counts are steadier. Meridian supports a non-revenue KPI with an average revenue per KPI, so you can model SQLs and still read results in pipeline dollars.
- Exposure: Use impressions or clicks where you have them. Meridian's guide warns that when spend stands in for exposure, periods of high ad cost "might be interpreted as high ad volume."
- Controls: Include the pricing flag, outbound volume, launch dates, brand query volume and sales headcount.
Brand search needs extra care. Its spend mostly follows demand that already exists, which is why Meridian's data guide lists Google query volume as a control for search ads. I'd keep brand query volume in the model and treat any large ROI it assigns to brand search with suspicion.
Now run the same rough count. A national model with four channels, four controls and three knots has 11 parameters, and 130 weeks gives about 12 data points per parameter, below the 15 that Meridian's own example treats as directional. Splitting into the nine U.S. census divisions creates 1,170 rows, but 45 SQLs a week works out to about five per division per week, and the smaller divisions will log many weeks near zero. Meridian's data guide advises excluding low-volume geos for exactly this reason.
How do you calibrate an MMM with experiments?
Calibration means turning experiment results and other knowledge into priors, the starting beliefs about each channel's ROI that the model then updates with data. Use experiments that match the MMM's channel, population, period and outcome, and carry each experiment's uncertainty into the prior instead of pinning the model to a single number.
Meridian's calibration guide calls incrementality experiments "perhaps the strongest basis" for priors, then adds that translating them "isn't a precise formula." It lists what to check before you use a result.
- Recency: Was the test run during the period the MMM covers?
- Duration: Was it long enough to capture carryover?
- Media granularity: Did it test the same channel definition the MMM uses, or one campaign inside it?
- Population: Did the test regions represent the market the model covers?
- Estimand: The MMM's counterfactual is zero spend, while a heavy-up test measures the lift from added spend. Those are different definitions of ROI.
That last mismatch matters for teams following the Lift Ladder. A six-week geo holdout read on SQLs measures a short-term effect, while the MMM's ROI covers the whole modeling window, carryover included. Zhang and her co-authors tested this in simulation and found that calibrating with ROAS priors "can significantly reduce the bias and uncertainty" in the model's estimates, and that priors set for the full modeling window reduced bias more than priors taken from short-term results.
Robyn's authors push in the same direction. Julian Runge, Koen Pauwels and Meta Marketing Science's Igor Skokan and Gufeng Zhou, Robyn's creator, open the calibration advice in their 2025 paper on Robyn with "Calibrate, calibrate, calibrate." I'd add one caution from Meridian's guide: an experiment is an estimate, and turning it into a prior "involves an additional layer of uncertainty beyond just the experiment's standard error." If the hypothetical company's search holdout produced a wide interval, its prior should be wide too. Meridian's CalibrationBuilder automates much of this translation and plugs directly into Meridian GeoX results.
How do you validate an MMM before it moves budget?
Validate an MMM by checking that it predicts held-out weeks reasonably, leaves no pattern in its errors, keeps its channel ranking when priors and controls change, reports intervals narrow enough to act on, draws response curves that make business sense and lands near an experiment it wasn't calibrated on. Passing all of them still doesn't prove the model is causal.
- Hold out recent weeks and check prediction. Meridian's holdout setting and its predictive accuracy metrics (R-squared, MAPE and wMAPE) are a first check that the structure isn't badly overparameterized.
- Read the residuals. A run of misses around a launch, a pricing change or a quarter end usually means a missing control.
- Test sensitivity. Refit with wider priors, and with one control added or removed. If the channel ranking flips, the data aren't deciding the answer.
- Read the credible intervals. If a channel's ROI interval runs from unprofitable to excellent, the model hasn't told you much about it. Meridian can also report the posterior probability that a channel's ROI is at least 1.
- Check the baseline and the curves. Meridian's guide flags a very low or negative baseline, or one channel dominating all the others, as results that don't make sense.
- Compare with an experiment you held back from calibration. If the model's estimate for that channel lands far outside the test's interval, find out why before you move money.
The limit behind all six is stated plainly in Meridian's model-fit guide: "directly validating the quality of causal inference is difficult and requires well-designed experiments." Prediction metrics "shouldn't be the primary way model fit is assessed," and the guide says a model that includes every confounder can be safer "even if this means the model is overfit." The required-assumptions page adds that whether all confounders are measured "is purely an assumption, and there is no statistical test to determine this from your data." A model that predicts well can still be wrong about cause.
When a model passes, base the budget call on marginal ROI at current spend rather than average ROI. Move money in steps that stay inside the spend range the model has seen. Then test the move with a heavy-up or a holdout, which sends you back down to rung 2 to check the model's call. That loop matters because Jin's team also found that the optimal mix from a model "has a large variance due to the variance of the parameter estimates."
What does MMM cost, and what should you do if you're not ready?
The software costs nothing: Google's Meridian is Apache-2.0 licensed and Meta's Robyn is MIT licensed. What an MMM costs a SaaS team is analyst and data engineering time, compute and the opportunity cost of decisions waiting on the model. If you fail the readiness gate, keep running geo tests and start collecting the dataset now.
- Meridian: A Python library that needs Python 3.11 to 3.13. Its README recommends at least one GPU and notes testing on a T4 GPU with 16 GB of RAM. Google opened it to everyone on January 29, 2025, with a partner program of more than 20 trained and certified measurement partners.
- Robyn: An R package that uses ridge regression and the Nevergrad library for hyperparameter search, with a Python API in beta since November 22, 2023. Its README says it's built for granular datasets and "especially suitable for digital and direct response advertisers with rich data sources."
- People: Someone has to set priors, read diagnostics and defend the result, and someone has to pipe weekly spend, exposure and CRM stage data from every platform. The Robyn paper's abstract says small and midsize businesses "often lack the resources to implement advanced proprietary modeling systems, which require specialized expertise and significant team investments."
- Opportunity cost: A quarter spent assembling data the model can't use yet is a quarter of tests you didn't run. Kantar found 31% of large advertisers now manage MMM internally, citing transparency, customization and lower costs, but those teams had the data first.
Here's how I'd decide the next move.
| Where you are | What I'd do next |
|---|---|
| Under two years of comparable weekly data, or SQLs were redefined recently | Keep running geo holdouts and start the weekly dataset now |
| Enough history, but channel budgets barely moved | Plan deliberate spend variation by region before modeling |
| History and variation, but no experiments | Run one geo test on your largest channel, then build with it as a prior |
| History, variation, experiments and an owner | Build a scoped model with a few channels and SQLs or opportunities as the KPI, then validate before moving budget |
| A few large enterprise deals a quarter | Skip MMM for now and test on leading indicators like demo requests |
Not being ready isn't wasted time. Every geo test you run now becomes a prior later, and every week of clean data shortens the wait. If you want help setting up that data or scoping a first model, that's the work I do in measurement and attribution.
Frequently asked questions
Is marketing mix modeling better than multi-touch attribution for B2B SaaS?
Neither is better, because they answer different questions. Multi-touch attribution tells you which tracked touchpoints came before a conversion, which helps with weekly campaign optimization. MMM estimates each channel's contribution, including what tracking misses, which helps with budget allocation across channels.
How much data do you need for marketing mix modeling?
Google's Meridian documentation recommends at least two years of weekly data for a geo-level model and three years for a national model, as a rule of thumb. The real requirement depends on how many channels and controls you model and how much your spend varied, so check data points per parameter before you trust a result.
Should a B2B SaaS MMM use pipeline or revenue as the KPI?
Usually SQLs, opportunities or pipeline, not closed revenue. Closed deals are sparse and lag marketing by months. Meridian accepts a non-revenue KPI with an average revenue per KPI, so you can model SQLs and still read the results in dollars.
Is Meridian or Robyn better for a SaaS team?
Both are free. Meridian is a Bayesian Python framework with geo-level modeling and built-in ways to turn experiments into priors, including GeoX integration. Robyn is an R package built on ridge regression with automated hyperparameter search. I'd pick the one your analyst can run and explain, since the hard part is the data, not the library.
Can an MMM measure LinkedIn Ads for B2B?
It can, if LinkedIn spend varied enough over time or across regions for the model to see its effect. Many B2B teams run LinkedIn at a steady always-on budget, which gives the model little to learn from. Run a geo holdout on LinkedIn first. It answers the question directly today, and later it becomes a prior for the MMM.